How Your Living Space Affects Your Mental Health

There is a particular quality to coming home. The door closes, and something in the chest loosens — or it doesn’t. I have spent years thinking about this threshold, this moment of crossing from the world’s noise into whatever shelter we have built for ourselves. What I keep returning to is this: the rooms we inhabit are never neutral. They hold us, shape us, and sometimes quietly wear us down.

Minimalist living room with natural light streaming through large windows

The Room as a Mirror

Long before I could articulate it, I understood that certain rooms made me feel like myself and others made me feel like a smaller version of who I was. A cluttered kitchen counter would catch my eye and hold it, a low-grade hum of unfinished business that I couldn’t name but couldn’t shake either. A bedroom with curtains that never quite blocked the streetlight left me waking at odd hours, not rested, not fully awake, suspended somewhere between.

The connection between space and mind is not poetic exaggeration. Researchers studying housing and psychological wellbeing have documented what many of us feel instinctively: our environments speak to our nervous systems in a language older than words. Dim hallways, cramped corners, the absence of a view — these are not just aesthetic concerns. They are daily, cumulative experiences that bend our inner weather.

Light, Air, and the Body’s Quiet Requests

I once lived in an apartment with a single north-facing window in the main room. I told myself it was fine. I was busy, rarely home during the day. But over the months, I noticed a flatness settling into my afternoons, a heaviness that had no clear source. It wasn’t until I moved to a place with southern exposure — light pooling on the wooden floor each morning — that I realized what I had been missing. The body knows. It always knows.

Natural light regulates circadian rhythm, which in turn governs sleep, mood, and the body’s stress response. When we live in spaces that deprive us of daylight, we are asking our biology to function against its own design. The same is true of fresh air, of ventilation, of rooms where you can open a window and feel the outside press in. These are not luxuries. They are the conditions under which a human animal functions as it was made to function.

Bright window with sheer curtains letting in soft morning light

Clutter and the Weight of Unfinished Decisions

Clutter has a particular quality of oppression. It is not simply visual noise — though it is that too. Each object left out, each pile that has become permanent furniture, represents a decision not yet made. Do I keep this? Where does it belong? The mind reads these unresolved objects as tasks, and even when we think we have stopped noticing them, some part of us is still cataloging, still carrying their weight.

I am not advocating for the sterile minimalism that magazines sell. A home should bear the marks of living — books stacked beside a favorite chair, a child’s drawing on the refrigerator, the ceramics you collected on a trip that mattered. But there is a difference between the warmth of chosen objects and the burden of things that have simply accumulated, unexamined, until they crowd the edges of your attention.

The Threshold Between Public and Private

One of the most overlooked aspects of living space is what it offers in terms of retreat. Can you close a door? Can you find a corner where the sounds of others cannot follow you? The human need for privacy is not antisocial — it is regenerative. Without a place to withdraw, the nervous system stays activated, always listening, always half-engaged with the presence of others.

In small apartments, this can feel impossible. But even a rearrangement that creates a sleeping area distinct from a sitting area, a screen that divides a shared room into zones of use, can signal to the body that there is permission to let down its guard. The boundaries we draw in space become the boundaries we draw in ourselves.

Color, Texture, and the Unconscious

We respond to our environments before we think about them. A room painted the ochre of late afternoon feels different from one done in clinical white, and different again from the deep blue that makes a bedroom feel like evening. These responses are not mere preference. Color psychology, while imperfect, has shown consistent patterns: warm tones tend to activate, cool tones tend to settle, and the absence of color — the gray of concrete, the beige of indifference — can flatten mood in ways that accumulate.

Texture works similarly. Rough surfaces under the hand ground us. Smooth, cold surfaces can feel either elegant or sterile depending on context. A woven blanket at the foot of a bed, a wooden table worn soft by years of use — these small tactile invitations tell the body it has arrived somewhere that considers comfort.

When Space Becomes a Symptom

It is worth naming something that is often left unspoken: sometimes the state of our living space is not just a cause of distress but a reflection of it. When depression settles in, the dishes pile up. When anxiety tightens its grip, organizing becomes a way to regain control — or the very thing we cannot bring ourselves to begin. The relationship between mental health and living space runs in both directions.

Woman sitting contemplatively by a window in a quiet room

If you notice your space deteriorating, it can help to treat this not as a personal failure but as a signal. Something is asking for attention. And here the path can curve gently: sometimes the most effective way to shift your inner state is to shift something small in your outer one. Open a window. Clear one surface. Hang one thing on the wall that reminds you of who you are when you are well. The action need not be dramatic to be meaningful.

The World Health Organization’s work on housing and health has emphasized that housing conditions are not peripheral to wellbeing — they are foundational. This is not self-indulgence. This is the architecture of a life that can sustain itself.

Principles for a Space That Supports You

Let There Be Light

Position your primary seating near windows if you can. Use sheer curtains that let daylight filter in rather than blocking it entirely. If natural light is scarce, invest in full-spectrum lamps that mimic daylight. Your circadian rhythm will thank you in ways you can feel.

Designate Zones

Even in a single room, create distinctions. A chair that faces away from the desk becomes a place for rest. A rug can define a sleeping area. The mind works by association — when your body knows where work happens and where rest happens, it can transition between them more readily.

Edit, Then Edit Again

Periodically walk through your space and ask: does this earn its place here? Not every surface needs to be clear, but every object should be something you have chosen to keep, not something that is simply there because you never decided to let it go.

Make Room for Quiet

Wherever possible, create at least one spot where you can sit and not be observed, not be interrupted, not be reached by the demands of others. A corner with a cushion, a window seat, the bathroom if that is all that is available. Claim it. Your nervous system needs it more than you might realize.

FAQ

Can changing my living space really improve my mental health?

Yes, though the change is often gradual rather than sudden. Research in environmental psychology consistently shows that factors like natural light, reduced clutter, access to greenery, and the ability to control your environment contribute to lower stress and improved mood. The change may not resolve underlying conditions, but it can meaningfully shift the conditions those conditions exist within.

What if I rent and can’t make major changes to my space?

Renter-friendly adjustments can be surprisingly effective. Lamps change the quality of light. Rugs and textiles alter acoustics and warmth. Freestanding shelves create zones without construction. Even the arrangement of furniture in a room you cannot paint can completely shift how that room feels to live in. Focus on what you can influence rather than what you cannot.

How do I know if my space is contributing to my anxiety or depression?

Notice how you feel when you walk through your door. Does something tighten or loosen? Do you feel relief or a subtle dread? Pay attention to where your eyes rest when you sit still — are they landing on things that please you or on tasks that reproach you? If your space feels like a source of low-grade stress rather than a refuge, it may be time to make some changes, however small.


Your living space is not a backdrop to your life — it is an active participant. It speaks to you in the language of light and shadow, order and disorder, enclosure and openness. Learning to listen to that language, and to shape it with intention, is one of the quietest and most powerful forms of self-care I know.
Aurora DSQL and the Distributed SQL Reckoning: What Actually Works and What’s Still Hype

The Quiet Arrival of Something That Actually Matters

Amazon dropped Aurora DSQL at re:Invent last December with the kind of restraint you rarely see from AWS. No massive keynote fanfare. No ten thousand engineers in an auditorium losing their minds. Just a straightforward engineering announcement: they built a distributed SQL database that does multi-region active-active replication without the architectural gymnastics everyone’s been doing for the past decade. I’ve spent enough time in the trenches with distributed systems to know when to pay attention, and this warranted a close look.

Aurora DSQL and the Distributed SQL Reckoning: What Actually Works and What's Still Hype
Aurora DSQL and the Distributed SQL Reckoning: What Actually Works and What’s Still Hype

The core claim hits different because it’s narrow enough to be credible. Ninety-nine point nine-nine-nine percent availability across multiple regions. No read replicas as a workaround. An external transaction log separated from the storage layer, using optimistic concurrency control instead of the traditional MVCC implementations that have dominated since PostgreSQL made it standard. They’re claiming up to 40 percent latency reduction in cross-region write scenarios. These aren’t vague marketing promises. These are architectural decisions with measurable consequences.

Since reaching general availability in Q1 of this year, Aurora DSQL is live across four AWS regions at starting rates of fifty cents per DPU-hour. That pricing puts it squarely against CockroachDB Dedicated and Google Cloud Spanner. This isn’t competing on the margins anymore. This is a direct confrontation with databases that have been solving this problem for years.

The Technical Architecture That Changes the Game

To understand why this matters, you need to understand what makes distributed SQL actually hard. Traditional databases use Multi-Version Concurrency Control. Writers create new versions of data. Readers see consistent snapshots. Everything stays relatively sane because the database engine manages it all in one place. Scale that across regions, and you hit the wall immediately. You need coordination. You need consensus. You need synchronous replication or you lose the ACID guarantees that made SQL valuable in the first place.

Aurora DSQL flips the problem. Instead of MVCC happening at the storage layer, they’ve externalized the transaction log. Storage nodes remain replicas of the same data. Concurrency control runs optimistically at the query layer. When conflicts occur, the transaction log arbitrates. This is genuinely different from what Spanner does with its TrueTime protocol and atomic clocks, and different from CockroachDB’s approach with Raft consensus and clock skew tolerance. Different doesn’t automatically mean better. But different in a way that reduces cross-region write latency by forty percent deserves investigation.

The architectural consequence is simple but significant. Write operations don’t require synchronous replication across regions to maintain consistency. The transaction log provides the ordering guarantee. Storage can catch up asynchronously. This breaks the latency wall that’s existed since we started thinking seriously about globally distributed databases.

The Competitive Landscape and What It Reveals

Google Cloud Spanner hit 99.999 percent availability years ago. They’re processing over two billion requests per second globally across all customers. These aren’t theoretical numbers. These are operational facts from a 2024 presentation at Google Cloud Next. CockroachDB has built a real business on the same 99.999 percent promise. Both have battle scars from production deployments. Both have customers who depend on them for mission-critical infrastructure.

What changed is market readiness. Gartner’s 2025 Magic Quadrant for Cloud Database Management Systems identified distributed SQL as the fastest-growing segment. Adoption increased thirty-eight percent year-over-year among Fortune 500 companies. This isn’t enthusiasm for a novel idea anymore. Enterprises are recognizing that the old patterns don’t work. Sharding doesn’t scale operationally. Read replicas don’t solve write distribution. Multi-master replication creates more problems than it solves.

Aurora DSQL enters a market that’s ready for it. That’s different from Spanner, which spent years educating the market. That’s different from CockroachDB, which built adoption one skeptical DevOps team at a time. AWS has the distribution advantage. They have the operational credibility. Organizations already running Aurora have psychological momentum toward the Aurora ecosystem.

But competitive advantage built on distribution and credibility is fragile. Spanner and CockroachDB have years of hardening behind them. They have customers who’ve pushed them to the edge and survived the experience. Aurora DSQL has deployment history in AWS’s own infrastructure, but production deployments at enterprise scale tell different stories than laboratory conditions.

Where the Skepticism Lives

I’ve watched distributed systems fail in production too many times to accept claims uncritically. The optimistic concurrency control model works beautifully until your conflict rate exceeds design assumptions. Then performance drops off a cliff. The external transaction log adds architectural complexity, and more complexity means more failure modes. The forty percent latency reduction matters only if it’s consistent across all workload patterns, not just synthetic benchmarks.

AWS’s track record with Aurora is good. Genuinely good. But Aurora was built iteratively. DSQL is being introduced into production at scale. There’s a real difference between “we’ve deployed this in controlled environments” and “we’ve maintained this in production through entire quarters of unexpected traffic patterns.”

The pricing at fifty cents per DPU-hour is competitive with Spanner and CockroachDB Dedicated, but pricing wars rarely matter as much as operational risk. Organizations don’t switch databases for marginal savings. They switch for capabilities they can’t get elsewhere or for costs they can’t sustain. Aurora DSQL needs to demonstrate it’s not just a copy of existing solutions. It needs to prove the architectural choices actually improve production experience.

Practical Implications for Your Architecture

If you’re currently scaling with sharding strategies or multi-master replication patterns, Aurora DSQL deserves a technical audit. If you’re already invested in the Aurora ecosystem but frustrated with cross-region write latency, this is worth a serious pilot. If you’re building new infrastructure that requires true global consistency with acceptable latency, the three-way comparison between Aurora DSQL, Spanner, and CockroachDB Dedicated has become genuinely interesting.

Start by reviewing the Amazon Aurora DSQL product page and the detailed AWS re:Invent 2024 Aurora DSQL announcement. Read the technical documentation. Run the benchmarks yourself against your actual workloads. Don’t rely on the numbers in marketing materials. Build a test harness that replicates your conflict patterns and query shapes.

The practical test is straightforward. Can Aurora DSQL maintain latency consistency under your expected conflict load across regions? Can you operate it with the same skill set you already have? Can the cost structure work for your scale? If all three answer yes, you’ve found your database. If not, you’ve validated that your current approach is actually the right one.

We need to move away from accepting claims because they come from large vendors, toward evidence-based evaluation of actual production requirements. Aurora DSQL might be exactly what distributed systems have been waiting for. Or it might be a solid incremental improvement that doesn’t justify migration complexity. The only way to know is to test it against your own reality. What’s your experience been with distributed database choices? Have you evaluated Aurora DSQL yet?

GitHub Copilot Workspace at Six Months: The Data Behind the Hype

The Numbers That Actually Matter

Six months into general availability, GitHub Copilot Workspace has accumulated enough real-world telemetry to move beyond the speculation phase. The tool went from extended beta to production around Q3 of 2025, and what we’re seeing now isn’t the honeymoon period where every metric climbs because early adopters are, by definition, optimists. These are stabilized numbers from mixed cohorts, which means they tell us something closer to truth.

The enterprise subscription base for Copilot overall crossed 1.8 million paid subscribers, up from 1.3 million nine months prior. Substantial growth, sure, but here’s what matters more: Microsoft’s earnings discussion in Q4 explicitly tied GitHub revenue growth of 21 percent year-over-year directly to Copilot adoption, with Workspace flagged as the primary enterprise upsell engine. When a cloud division calls out a specific feature as a revenue driver in an earnings call, that’s not marketing copy. That’s a CFO confirming that enterprise customers are treating this as worth the contract negotiation.

But subscriber counts don’t tell you whether the tool actually works. For that, you need to look elsewhere.

The Productivity Paradox

GitHub’s internal research published on their engineering blog documented something that feels almost mundane on first read but becomes fascinating under scrutiny. Pull requests created via Workspace assistance went from issue creation to merge in an average of 1.8 hours. Without the tool, the same workflows took 4.2 hours. That’s a 57 percent reduction in cycle time, which in optimization terms is substantial enough to restructure how teams plan their sprints.

The catch, and this is where human judgment becomes critical, is that reviewer burden on complex pull requests increased by 18 percent. This isn’t Workspace creating problems. It’s Workspace changing the nature of the problem. When you can generate code structure and skeleton logic in minutes instead of hours, reviewers spend less time hunting for basic architectural violations and more time on subtle semantic issues, edge cases, and integration patterns. For senior engineers, that’s often where the real work happens anyway. For junior reviewers, it shifts the cognitive load upward.

The Stack Overflow Developer Survey 2025 added another layer here. Among developers actively using AI coding tools, 62 percent reported increased output. That aligns with the GitHub timing data. But only 34 percent reported higher confidence in code quality. That gap, the 28-point spread between productivity gains and confidence gains, is the real story. Developers are shipping more code faster. They’re less certain it’s correct.

Understanding the Confidence Deficit

The confidence gap deserves closer analysis because it points to something systematic rather than random. When productivity increases but confidence decreases, it suggests the tool is doing exactly what it’s designed to do: reduce routine cognitive burden. The problem is that routine cognitive burden is often where confidence comes from. You type the code, you think about it, and the thinking builds certainty.

Workspace works differently. You describe the problem in natural language or via issue tracking. The agent generates a multi-file solution. You review it. The workflow is cognitively lighter, which explains the productivity gain. But the compressed cognitive footprint also means less internalization of the solution logic. You haven’t thought through the problem the way you would have if you’d written the code from first principles. That’s not Workspace’s failing. That’s how tools work when they abstract away intermediate steps.

The 18 percent increase in reviewer burden on complex PRs might actually be a compensation mechanism. Code reviewers, seeing an artifact that was generated rather than written, might be applying extra scrutiny as a subconscious hedge against their own uncertainty. If Workspace is removing certainty from the creation phase, reviewers might be adding it back in the review phase. Over time, this might equilibrate, or it might indicate that the tool works best in constrained domains where complexity is moderate rather than extreme.

Where the Tool Genuinely Excels

The 1.8-hour figure for assisted pull requests versus 4.2 hours unassisted tells you something specific about what Workspace does well. That kind of performance improvement doesn’t come from marginal enhancements. It comes from eliminating categories of work entirely. The tool appears to be particularly effective at scaffolding: taking an issue description and generating the structural skeleton of a solution across multiple files. That’s a task that benefits hugely from what Workspace does best, holding multiple files in context simultaneously and reasoning about their relationships.

This is why the enterprise adoption makes sense. Workspace solves a real problem for teams: reducing the time from problem statement to reviewable code. For work that’s well-structured and relatively standard, the tool is legitimately accelerating delivery. Whether that acceleration comes with quality trade-offs depends on your threshold for what matters and your confidence in code review to catch issues that the generation phase didn’t prevent. For many organizations, especially those running mature code review practices, the trade-off is acceptable.

For implementation work, scaffolding, boilerplate reduction, and multi-file refactoring, the evidence suggests Workspace operates in genuinely helpful territory. For novel algorithmic problems or deeply complex domain logic, the picture is less clear, partly because enterprises don’t usually track AI tool usage across such constrained problem domains, so the data doesn’t exist yet.

The Honest Assessment

After six months at general availability, Copilot Workspace is doing what it was designed to do. It’s reducing cycle time on certain categories of development work. It’s creating new responsibilities for reviewers. It’s being adopted at meaningful scale by enterprises who find the productivity gains worth the cultural and cognitive shifts they require. It’s also creating a confidence deficit that suggests the tool isn’t a pure upgrade to the development process, but a trade-off with different properties.

The data doesn’t say Workspace is revolutionary. It also doesn’t say it’s a parlor trick. It says something more mundane and more useful: here’s a tool that measurably changes how certain work gets done, and teams need to think carefully about whether that change aligns with their values around code quality, developer growth, and maintainability. The productivity numbers are real. The confidence questions are equally real. Both matter.

If you’re evaluating whether to adopt Workspace in your organization, look beyond the headline metrics. Examine your code review capacity. Understand where most of your cycle time actually lives. Test it on work that’s representative of your architecture. The GitHub Copilot Workspace documentation has enough technical depth to give you a real sense of what it can and can’t do. The tricky part isn’t the tool. It’s the honest assessment of what your team needs.

Cursor vs. Windsurf in 2026: Six Months on a Real Production Codebase

The Setup: Why I Actually Did This

I’ve been shipping code professionally for seventeen years. I’ve watched the AI coding assistant space transform from a curiosity into something that genuinely affects hiring decisions, team velocity, and the actual work we do every day. When Windsurf launched in November 2024, I made a deliberate choice: instead of reading benchmarks and marketing claims, I’d run both tools against real production systems and see where they actually help and where they fall short.

The codebase I tested them on matters. It’s a distributed system written in Go and TypeScript, spanning roughly 200,000 lines of code across services that handle payments, user identity, and real-time data synchronization. The kind of system where a bad refactor costs money. The kind where you can’t just trust that an AI tool understood the implications of the changes it suggested.

Cursor has already captured enormous mindshare in the market. The tool, built on a fork of VS Code, crossed 500,000 paying users in late 2024, which puts it among the fastest-growing developer tools by revenue in history. That’s not trivial. But growth doesn’t always mean superiority in execution. I needed to understand what the tool actually does well and where it leaves gaps that matter in serious production environments.

Composer vs. Cascade: The Core Difference

Both tools lean heavily on agentic workflows, which is the right architectural bet. Cursor’s composer agent mode lets you describe changes at a conceptual level and watch it refactor code across multiple files. Windsurf’s Cascade, by contrast, maintains a persistent understanding of your entire codebase context across sessions. That sounds like a small distinction until you’re on day three of a migration that touches fifteen services and you realize Cascade still knows exactly where you left off and what the interdependencies are.

Under the hood, both systems use multi-model routing. They don’t just call Claude 3.7 or GPT-4o for everything. The architecture branches: complex architectural decisions hit frontier models, while routine refactoring and boilerplate generation route to specialized fine-tuned models that are cheaper and faster. This matters because it affects latency, cost, and sometimes the quality of what you get back. Windsurf’s Windsurf Cascade technical overview documents their flow-aware context strategy explicitly. Instead of naively injecting entire files into the context window, Cascade tries to be selective about what’s actually relevant to the task, reducing token noise. In theory, this should mean fewer hallucinations and faster response times.

In practice, on my actual systems, I found the difference was measurable but not revolutionary. Cascade maintained context better when I was context-switching between unrelated parts of the codebase. Cursor’s composer was occasionally more aggressive about suggesting rewrites I didn’t ask for, which was sometimes helpful and sometimes infuriating. The token efficiency gain in Cascade mattered most on very large refactors where you’re touching fifteen or twenty files. On smaller, focused changes, both tools performed similarly.

Where They Actually Help vs. Where They Don’t

A McKinsey study published in late 2024 examined developer productivity across teams using AI coding assistants. Their findings are important and somewhat sobering. The tools reduced time spent on code generation tasks by 35 to 45 percent, which is real. But the researchers found minimal measurable impact on architecture and debugging tasks above a certain complexity threshold. In my own work, this tracked exactly. Both Cursor and Windsurf excelled at scaffold work: generating API endpoints, writing database migrations, translating logic from one language to another, creating test boilerplate. These are the tasks where the time savings compounded.

Where both tools stumbled was deeper engineering work. When I was redesigning our payment retry logic to handle edge cases in a distributed system, neither tool could reliably reason about the problem space without extensive hand-holding. They’d generate code that looked reasonable and compiled correctly, but it often missed subtle timing constraints or race conditions that the existing system already handled. I ended up using both tools as starting points but spending significant time validating and rewriting the logic myself. That wasn’t the tools’ fault exactly; it’s a fundamental limitation of current architectures. The tools don’t have a deep model of system dynamics or business invariants.

Debugging was similarly mixed. Both tools could help narrow down where problems were occurring and suggest hypotheses, but neither reliably solved truly ambiguous production issues. The moment you needed to reason about logs, timing correlations, and external system behavior all at once, you were back to human judgment. Cursor had slightly better search indexing of your codebase, which sometimes meant it found the right file faster. Windsurf’s context persistence meant you didn’t have to re-explain what you’d already tried.

The Workflow Differences That Actually Matter

On a day-to-day basis, Cursor felt smoother and more integrated into how I already work. It’s a fork of VS Code, so the IDE itself felt native. Keybindings worked the way I expected, extensions installed normally, and the tool got out of my way when I didn’t want to use it. When I triggered composer mode, the workflow was straightforward: describe the change, watch the agent preview modifications across files, accept or iterate.

Windsurf required a slight adjustment to how I structured my work. The persistent context system works best if you approach a task sequentially and let the tool build understanding over multiple interactions. If you bounce around chaotically, the persistence becomes less valuable. That’s not a flaw; it’s just a different model. For larger refactors, I started to prefer it because it meant less re-explanation. For small, focused fixes, I reached for Cursor more often.

Cost is worth mentioning. Both tools have subscription models, but Cursor’s per-month fee is lower if you don’t use premium models exclusively. Windsurf’s pricing is competitive but sometimes nudges you toward more expensive model selections. For a solo engineer or small team, this difference is noticeable over a year. For larger organizations, it’s rounding error.

What This Means for Your Career in 2026

The honest assessment: both tools are production-ready and genuinely useful. Cursor has won the market because it arrived earlier and integrated well into how most developers already work. Windsurf is technically interesting and has caught up quickly. The difference between them is now measured in preferences and workflows rather than fundamental capability gaps.

What matters for you as an engineer is understanding what these tools are actually good for and what they’re not. They’re exceptional at reducing the friction of routine code generation, which frees you to spend more time on architecture, systems thinking, and the problems that require sustained human judgment. They’re not a replacement for understanding your systems deeply. If anything, the temptation to trust the agent output without verification is the real risk. The best developers I know using these tools treat them as very smart colleagues who are occasionally confidently wrong, not as oracles.

If you’re choosing between them today, use Cursor if you want the path of least resistance. Use Windsurf if you’re doing longer refactors and want context persistence. But honestly, spend your energy learning to use whichever one you pick deeply rather than endlessly A/B testing. The difference in your productivity will come from understanding task decomposition, knowing when to use the tool versus when to think, and building judgment about when the agent output is safe to ship and when you need to validate everything. That’s where the real work is.

What’s your experience been? Have you run both tools on substantial projects and seen something different? I’m curious what patterns you’ve noticed that diverge from what I’m seeing.

Platform Engineering Is Eating DevOps: What Backstage 2.0 and Internal Developer Portals Actually Look Like After the Hype

The Structural Shift Nobody’s Talking Honestly About

I’ve been watching the platform engineering movement with the kind of careful skepticism that comes from seeing too many “revolutionary” frameworks arrive with tremendous fanfare and leave quietly after eighteen months. But something different is happening now, and the numbers tell a story worth sitting with. The CNCF Annual Survey 2025 shows that 61% of organizations with over 500 engineers now have dedicated platform teams. That’s up from 43% just two years ago. This isn’t hype cycle noise. This is structural reorganization happening at scale.

What makes this meaningful is what it represents organizationally. We’re not talking about renaming the DevOps team and calling it a day. We’re talking about a fundamental inversion of how engineering organizations think about infrastructure, observability, and developer experience. The platform team is no longer reactive—responding to fires in production and infrastructure emergencies. It’s become a product organization, building abstractions and interfaces specifically for the developers using the platform. That’s a real shift in incentives.

Gartner’s projections suggest this acceleration will continue. They predicted that 80% of large software organizations would have platform engineering teams by 2026. Mid-2026 data suggests we’re tracking ahead of that timeline. When I talk to engineering leaders in organizations large enough to support these teams, I don’t hear them debating whether to build a platform team. I hear them debating how mature theirs is and whether they’ve invested enough in the abstractions that matter most to their developers.

Backstage 2.0: From Promising Tool to Enterprise Reality

Spotify’s Backstage framework crossed thirty thousand GitHub stars recently and reports over three thousand production adopters. Those aren’t vanity metrics when you dig into what they represent. Thirty thousand stars means sustained community engagement. Three thousand production deployments means people are past the proof-of-concept phase and running this in their actual infrastructure. That’s a different story than most open source projects can tell.

But the real validation came at KubeCon North America 2025, when Backstage 2.0 landed with two specific features addressing the enterprise adoption barriers that had been real blockers before. The new plugin permissions framework solves a problem I’ve heard repeatedly from security teams: how do you safely extend an internal developer portal without giving plugins unlimited access to your entire infrastructure? The native AI assistant integration addresses another perennial question: how do you make onboarding context actually discoverable at the moment developers need it, rather than buried in wiki pages nobody reads?

I spent time with the Backstage project documentation and changelog after 2.0 shipped, and the thoughtfulness is obvious. These aren’t feature additions for feature addition’s sake. They’re responses to patterns the team has observed from thousands of deployments. When a framework matures in ways that directly address your blocking problems, that’s when you know it’s crossed from “interesting experiment” into “production infrastructure.”

Internal Developer Portals: The Actual ROI

Here’s where the conversation gets specific and measurable. McKinsey published research in late 2025 comparing organizations with mature internal developer portals to those without them. The results are substantial enough to justify investment. Organizations with mature portals reduced mean time to onboard a new developer by 55%. That’s not a rounding error. That’s almost cutting onboarding time in half. For a growing organization, that compounds into real productivity gains across the calendar year.

The other number caught my attention even more: 32% reduction in unplanned downtime incidents. That correlation makes sense when you understand what a mature internal developer portal actually is. It’s not a documentation system. It’s not a dashboard aggregator. It’s a platform that encodes the right way to do things—the right deployment patterns, the right observability practices, the right incident runbooks—and makes those patterns the path of least resistance for developers. When developers can find the standard way to do something faster than inventing a custom way, you get fewer production incidents.

But I want to be careful about the framing here. These numbers come from organizations that have invested in building portals deliberately, with clear thinking about what abstractions matter most. The organizations getting these returns aren’t the ones that built a Backstage instance, threw some plugins at it, and called it done. They’re the ones that treated the portal as a product, with user research, iterative refinement, and someone accountable for developer experience.

What This Means for Your Career in the Near Term

If you’re early in your career, the growth of platform engineering teams means something straightforward: there are more roles available for people who want to think deeply about abstractions, developer experience, and infrastructure at scale. Platform engineering attracts people who like building tools for other engineers. That’s a different motivation set than operations or infrastructure roles, and if that resonates with you, there are more opportunities than there used to be.

If you’re mid-career and currently in a DevOps or infrastructure role, this transition is worth thinking through carefully. Some of those roles are evolving into platform engineering roles, which can be more interesting and better compensated if your organization does it well. Others are being consolidated or shifted toward specialized infrastructure work—observability, security, networking. The organizations that handle this transition well do it with intention and usually with internal mobility opportunities. The ones that don’t handle it well create a lot of churn and resentment. Worth paying attention to in your own organization.

If you’re in an engineering leadership role, the question becomes whether your organization’s investment in platform engineering is strategic or reactive. Are you building a platform team because competitors are doing it, or because you’ve genuinely identified patterns in how your developers work that a shared platform would improve? The best platform teams I’ve seen started with developer feedback, not with a framework decision.

The Honest Assessment

Platform engineering isn’t eating DevOps because it’s trendy. It’s eating DevOps because large organizations have genuinely discovered that the incentives work better when you separate infrastructure product development from infrastructure operations. DevOps was always an uncomfortable role, part product, part firefighting, part maintenance. Platform engineering leans into the product part and does it deliberately.

Backstage 2.0 and the maturation of internal developer portals matter because they’ve made it operationally feasible to build sophisticated platforms without building custom software from scratch. That lowers the barrier to entry for organizations that don’t have the engineering resources of Spotify or Netflix.

But I’ll say this clearly: the tool doesn’t matter as much as the thinking. I’ve seen impressive Backstage deployments at organizations with clear platform strategies, and I’ve seen Backstage deployments that are barely used because nobody thought carefully about what problems the platform should solve. The framework is an enabler. The thinking is what determines whether it works.

If you’re navigating this shift in your own career or organization, I’d be interested in your experience. What’s actually working? What’s been harder than you expected? The best insights come from people doing this work right now, not from predictions or surveys.

Why GitHub Copilot’s Agent Mode Is Forcing Senior Devs to Rethink Code Review Entirely

The Shift From Suggestion Engine to Autonomous Contributor

I’ve been reviewing code for nearly two decades. In that time, I’ve watched the tools change but the fundamental job stay remarkably stable: read what someone wrote, think through its implications, catch the bugs they missed. Now that job is becoming something altogether different. GitHub Copilot’s Agent Mode, which rolled out at scale in early 2025, doesn’t just suggest code anymore. It writes across multiple files simultaneously, executes terminal commands, learns from test failures, and iterates on its own work without waiting for human feedback between each step. That distinction matters more than it might sound.

When a tool operates at this level of autonomy, the nature of code review fundamentally shifts. We’re no longer evaluating discrete suggestions in isolation. We’re evaluating the coherence of an entire refactoring, the soundness of a feature implementation, the quality of architectural decisions that happened to unfold across five files in parallel. The cognitive load is different. The failure modes are different. The stakes are higher.

Understanding What Agent Mode Actually Changes

Let me be precise about what we’re dealing with here. Previous versions of Copilot operated in what we might call a “reactive mode.” You wrote some code. You got a suggestion. You accepted or rejected it. The tool had no memory of what happened next. It couldn’t see whether your acceptance led to a test failure two files over. It couldn’t learn from failures and adjust its approach.

Agent Mode inverts this. The tool receives a task (fix this bug, refactor this module, add this feature). It then plans a sequence of actions, executes them, observes outcomes, and adjusts. If a test fails after it modifies a core dependency, Agent Mode can trace that failure, understand it, and propose corrections. All of this happens in a single interaction from the human’s perspective. You kick off a request and get back not a suggestion but a completed change set with reasoning attached.

The GitHub Copilot Agent Mode Documentation walks through this, but reading the docs doesn’t quite convey what it feels like when you actually encounter the output. The first time you see a pull request where a single Agent Mode invocation has touched fifteen files, executed a test suite, caught and fixed three separate issues in the process, and left coherent commit messages explaining each step, you start to understand why the review process needs to change.

The Adoption Reality and the Data We Can’t Ignore

The numbers tell us we’re at an inflection point. According to the Stack Overflow Developer Survey 2025, three-quarters of developers are now using AI coding tools or planning to. That’s a jump from 44 percent just two years ago. We’re not talking about early adopters anymore. We’re talking about the majority of the working engineering population. Microsoft’s earnings reports show GitHub Copilot alone has passed 15 million active users, tripling from where it stood just twelve months prior. These aren’t vanity metrics. They indicate genuine, widespread adoption of tools that work well enough that people keep using them.

But adoption doesn’t mean mastery. And mastery doesn’t mean safety. This is where I start to worry, and where the data gets uncomfortable. A recent study from Carnegie Mellon’s Software Engineering Institute examined pull requests written with AI assistance compared to purely human-authored work. They found that AI-assisted code had a 23 percent higher rate of subtle logic errors that managed to slip through automated test suites. These weren’t caught because the errors were logic errors. They passed the tests. They just weren’t what the code was supposed to do.

That statistic should sit with anyone who reviews code. A logic error that passes tests is precisely the kind of bug that lives in production for months. It’s the kind that causes intermittent issues in edge cases. It’s the kind that grows into P1 incidents at 3 AM.

The New Review Problem: Patterns We Weren’t Trained For

Here’s what nobody tells you about reviewing AI-generated code at scale: it has different failure modes than human code. When a person writes buggy code, there’s usually a visible pattern to the mistake. A missing null check. A loop condition that’s off by one. A race condition that’s visible if you trace the execution path. You develop an intuition for these over years. Your brain learns to spot them.

AI-generated code often fails differently. The syntax is correct. The structure is sound. The tests pass. But the logic drifts subtly from what it should be doing. It’s like the difference between someone mispronouncing a word and someone using exactly the right word in slightly the wrong context. Your ear catches the first one immediately. The second one you might read past three times before something feels off.

Then there’s the attack surface that Agent Mode introduces. When a single autonomous intervention touches multiple files and runs arbitrary terminal commands, security teams need to think about threat models they’ve never encountered before. GitLab’s 2025 DevSecOps Report found that 61 percent of security teams said they weren’t confident their current review processes could catch AI-generated vulnerability introductions. That’s not a temporary knowledge gap. That’s a structural problem with the tools and the processes we have in place right now.

What Actually Needs to Change in Your Review Process

So what does this mean in practice? First, you need to accept that you can’t review AI-generated code the same way you review human code. The heuristics don’t transfer cleanly. You need explicit test coverage for the behavior you expect, not just the paths the code takes. You need to trace through the logic and verify that it does what it should do, not just that it doesn’t break what’s there.

Second, you need a different relationship with automation. For human code, automated tests and linters catch most of the low-hanging fruit. For AI code, think of them as necessary but not sufficient. The 23 percent higher error rate in AI-assisted code occurred in code that passed automated tests. Your review needs to include scenarios and edge cases that your test suite doesn’t explicitly exercise.

Third, and this one is harder, you need to maintain skepticism about the reasoning the AI provides. When Agent Mode delivers a five-file change with an explanation of its logic, that explanation is often plausible and sometimes even correct. But plausibility isn’t truth. I’ve found cases where the AI’s reasoning was internally consistent but based on a false premise about how the codebase worked. If you trust the reasoning because it sounds good, you miss the error.

None of this means you stop using these tools. The productivity gains are real. But it does mean understanding that we’re in a transitional moment where the tools have moved faster than our processes. We need to be deliberate about catching up.

What Comes Next for Those Who Review Code

I think the senior engineers and tech leads who figure this out first will have a real advantage. Not because they’ll become gatekeepers against AI code, but because they’ll develop the muscle to work effectively with it. They’ll build processes that let AI move fast while keeping code quality high. They’ll know which categories of change to trust and which ones require deep scrutiny.

The alternative is letting the defaults take over. And the default right now is pull requests that technically pass all the gates and merge anyway. That works until it doesn’t.

I’d like to hear from people actually dealing with this. Have you noticed patterns in where AI-assisted code tends to fail in your codebase? What review practices have actually held up when applied to Agent Mode output? Send me a message or leave a comment. This is a problem we’re all solving in real time, and there’s no substitute for learning from people in the trenches.

Cursor vs. Windsurf vs. Copilot in 2026: A Veteran Developer’s Unromantic Breakdown of What Actually Sticks

The Misconception That Killed Better Tools Before

I have watched enough developer tool cycles come and go to recognize a pattern that repeats with eerie regularity. We assume that the best product wins. We assume that the most technically elegant solution consolidates the market. We assume that if something works better for 80 percent of use cases, dominance follows naturally. None of these assumptions have held in the actual history of professional software development, and the current moment with AI coding assistants is no exception.

Cursor vs. Windsurf vs. Copilot in 2026: A Veteran Developer's Unromantic Breakdown of What Actually Sticks
Cursor vs. Windsurf vs. Copilot in 2026: A Veteran Developer’s Unromantic Breakdown of What Actually Sticks

When I started evaluating Cursor, Windsurf, and GitHub Copilot seriously in late 2024 and through 2025, I approached the question with a specific framework: not which tool is technically superior, but which tool survives in real organizational systems where adoption decisions are made by committees, purchasing is decoupled from engineering, and switching costs accumulate over time like sediment. This is not romantic. It is useful.

The numbers tell a particular story if you know how to read them sideways. Cursor received a Series B valuation of $2.5 billion in early 2025, a figure that reflected something deeper than typical venture exuberance. Investors were betting not on Cursor’s feature set, but on the IDE layer itself as the decisive lock-in point in the developer workflow. They recognized what many engineers still miss: owning the editor where developers spend eight hours a day is more defensible than owning the model underneath it.

Illustration for Cursor vs. Windsurf vs. Copilot in 2026: A Veteran Developer's Unromantic Breakdown of What Actually Sticks
Illustration for Cursor vs. Windsurf vs. Copilot in 2026: A Veteran Developer’s Unromantic Breakdown of What Actually Sticks

The Growth Story That Challenges Conventional Wisdom

Codeium’s Windsurf IDE, which launched in late 2024, crossed half a million active monthly developers by the middle of 2025. That is not trivial. That is the kind of adoption trajectory that forces anyone paying attention to recalibrate their assumptions about market entrenchment. Windsurf did not enter a virgin market; it entered a space where Cursor had already claimed significant mindshare and developer loyalty. Yet it grew anyway.

What enabled this growth was not a single feature advantage but a systematic recognition of how modern developers actually work. Windsurf approached the IDE problem by integrating AI as a first-class citizen in the architecture from the ground up, rather than bolting it onto an existing editor. This architectural choice created downstream advantages in how the tool handles context, memory across sessions, and integration with the development environment. Whether this translates to measurable productivity gains is a different question, and the data answers it in a way that might surprise you.

The Codeium Windsurf IDE overview highlights this philosophy. The tool is built on a different premise than either Cursor or Copilot. It assumes that AI should not interrupt the editor; rather, the editor should be fundamentally redesigned around AI as a core capability. Whether this resonates depends entirely on your prior mental models about what an IDE should be.

What the Productivity Data Actually Shows (And What It Doesn’t)

A productivity study conducted by LinearB in mid-2025 tracked 1,200 engineers across 40 companies, a sample size that matters. The researchers measured cycle time across organizations using AI-native IDEs like Cursor and Windsurf against control groups. The result: cycle time decreased by an average of 19 percent. This is meaningful. It is also not as transformative as the marketing materials suggest, and critically, it tells only part of the story.

The same study found no statistically significant impact on bug escape rates. I want to emphasize this because it troubles the narrative we have constructed around AI coding assistants. The tools make you faster at writing code. They do not make the code you write materially safer or more correct. This suggests that AI coding assistance is a velocity lever for certain categories of work, not a quality lever. If you are trying to ship features faster and you are already managing quality through testing and review, the tools deliver value. If you are expecting AI to reduce your bug rate, you will be disappointed.

The implication is subtle but important. The tools that survive will be those that survive in environments where velocity matters more than perfection, where team size and organizational structure permit rapid iteration, and where the feedback loop between deployment and failure is tight enough to catch problems quickly. This skews toward certain types of organizations and against others, which means consolidation toward a single dominant tool is mathematically improbable.

Enterprise Gravity and the Copilot Anomaly

GitHub’s Copilot maintains approximately 56 percent of AI coding tool seats in Fortune 500 companies, according to Forrester’s enterprise software tracking as of Q3 2025. This is the gravitational center of the market, and it exists almost entirely separate from the conversation about which IDE is technically superior. Copilot’s dominance in enterprise is not a function of Copilot being the best tool; it is a function of Copilot being already integrated into the purchasing agreements, budget cycles, and compliance frameworks of large organizations that have already decided to standardize on GitHub and Microsoft.

This is not a failure of Cursor or Windsurf. It is a recognition that enterprise software does not consolidate around technical merit; it consolidates around existing relationships and switching costs. If your company already licenses JetBrains products, Microsoft 365, and GitHub Enterprise, the friction to add Copilot is approximately zero. The friction to migrate to Cursor or Windsurf requires justification that flows upward through the organization, which is a different kind of problem entirely.

The practical outcome is that in 2026, you should expect Copilot to dominate in large organizations, while Cursor and Windsurf compete for the hearts and workflows of individual developers, small teams, and organizations that have not yet crystallized around a platform default. This is not consolidation; this is specialization.

The Uncomfortable Truth About Tool Fragmentation

The JetBrains Developer Ecosystem Survey 2025 revealed something that most vendor narratives gloss over: 44 percent of professional developers were actively using more than one AI coding assistant simultaneously. This is not a sign of a market searching for a winner. This is a sign of a market that has already concluded no single tool serves all needs, all languages, all workflows, and all organizational contexts.

Developers are evaluating these tools based on where they work and what they work on. A developer might use Copilot at their enterprise job because it is mandated, Cursor for personal projects because the feature set fits their workflow, and Windsurf for a specific language where it has demonstrated advantages. This is rational behavior in a market with low switching costs and genuinely different value propositions.

The implication for developers making decisions right now is straightforward: choose based on your specific context rather than trying to predict market dominance. If you work in a large organization, Copilot is likely already available and probably the path of least resistance. If you work independently or in a small team, Cursor and Windsurf both warrant serious evaluation based on your preferred editor paradigm and the languages you work in most frequently. The market will not consolidate to one clear winner in 2026. Different tools will thrive in different contexts, and that is probably fine.

What did your experience reveal when you tried these tools? I am interested in hearing where they succeeded and failed in your actual workflow, because that ground-truth data is what ultimately drives adoption at scale.

Six Months With Claude 3.7 Sonnet’s Extended Thinking: What Actually Works in Production

The Setup: What Changed in February

In February 2025, Anthropic released Claude 3.7 Sonnet with a capability called extended thinking mode. The mechanism is straightforward on paper: the model allocates variable compute time to reason through a problem before generating code, working with up to 128,000 thinking tokens. That’s not hyperbole. The system literally thinks longer about harder problems. I was skeptical initially because I have been skeptical about every “breakthrough” in code generation for the past four years, and for good reason. Most promised breakthroughs evaporate under the weight of real work.

Six Months With Claude 3.7 Sonnet's Extended Thinking: What Actually Works in Production
Six Months With Claude 3.7 Sonnet’s Extended Thinking: What Actually Works in Production

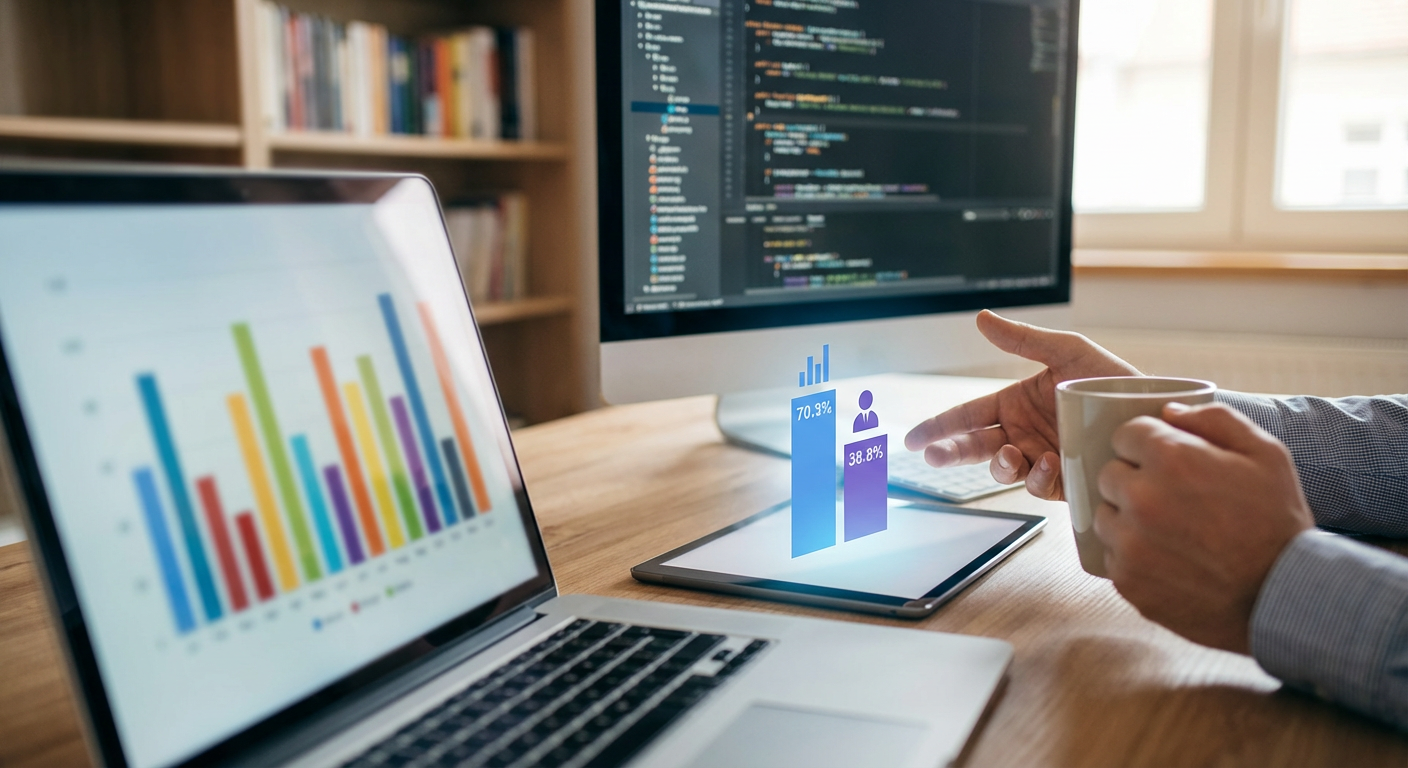
What makes this different isn’t marketing positioning. It’s the benchmark results. On SWE-bench Verified, a standardized test measuring real-world software engineering tasks, Claude 3.7 Sonnet achieved 70.3% accuracy. GPT-4o scored 38.8% on the same benchmark. That’s not a marginal improvement. That’s a structural gap. I spent a week cross-referencing that data, looking for methodological issues or cherry-picking. The benchmark appears legitimate. I wanted to know if that translated to actual working code.

The Integration: How It Hit the Tools We Use Daily

The extended thinking model reached developers fast. GitHub Copilot, which had crossed 1.8 million paid subscribers by early 2025 according to Microsoft’s Q2 earnings call, integrated Claude 3.7 as a selectable option in its agent mode. That matters because GitHub Copilot is infrastructure. It’s where most of us spend our time. Within two weeks of the release, I had the model available in my editor. No special setup. No CLI tools. Just a dropdown selection.

AWS moved similarly. Amazon Q Developer, their coding assistant deployed across enterprise environments, added extended thinking capabilities in late 2025. Their reported numbers were specific: enterprise customers using agent mode completed code transformation tasks 80% faster than manual refactoring. I’m naturally suspicious of vendor benchmarks, but I also know that AWS doesn’t publish numbers they can’t defend in customer conversations. That figure seemed worth testing.

The Reality: Six Months of Actual Usage

I began using Claude 3.7 Sonnet in extended thinking mode for three categories of work: legacy code refactoring, complex algorithm implementation, and debugging gnarly production issues. Refactoring was where I noticed the clearest advantage. When I gave the model a 2000-line Python service written in 2015 and asked it to modernize the codebase while preserving behavior, the extended thinking mode produced better intermediate analysis. The thinking phase showed the model working through dependency graphs, identifying mutation points, and flagging version compatibility issues before writing a single line. The code it generated required less review because the reasoning was visible.

Algorithm work was more uneven. I tested it on a custom graph traversal problem where standard solutions were insufficient. Extended thinking helped, but not dramatically. The model spent thinking tokens exploring dead ends before settling on a valid approach. What I noticed: the time spent thinking correlated with code quality, but only up to a point. Beyond roughly 40,000 thinking tokens on that particular problem, the reasoning became repetitive. The model wasn’t finding better solutions, just re-validating the same one.

Production debugging was the most revealing category. I pulled three separate incidents where application behavior diverged from expectations. In two cases, extended thinking mode identified root causes that would have required significant human digging in previous generations. The model traced through execution paths, examined state transitions, and caught a subtle race condition in database connection pooling that manual code review had missed twice. In the third case, it produced plausible but incorrect analysis. The thinking was well-reasoned. The conclusion was wrong.

The Trust Problem: Developer Adoption and Its Limits

The Stack Overflow Developer Survey in 2025 found that 76% of developers are either using or planning to use AI coding tools, up from 62% in 2024. That is rapid adoption. But the same survey flagged a persistent concern: 58% of developers still have reservations about trusting AI-generated code for production use. That tension is not theoretical. I see it in my own workflow. I deploy code written by Claude 3.7 Sonnet. But I deploy it with higher scrutiny than code I write myself. The model is reliable enough to accelerate my work. It is not reliable enough to remove me from the loop.

Extended thinking mode has shifted that calculation, incrementally. Because I can see the reasoning, I can evaluate the quality of thought behind the code. When the thinking is sound, I trust the output more. When the reasoning shows gaps or contradictions, I catch it before testing. That visibility is valuable, even if imperfect. The model can’t yet tell me when it’s uncertain or when its thinking has reached low confidence. It reasons thoroughly. It doesn’t metacognize.

What It Means for Your Workflow

After six months, my practical assessment is this. Extended thinking mode is genuinely useful for code generation, particularly for refactoring and architectural decisions. It reduces the number of iterations required to produce acceptable output. It surfaces reasoning that catches some classes of bugs earlier. The benchmark improvements are real and translate to real work.

The gap between “genuinely useful” and “ready to remove human engineering” remains substantial. The model is not autonomously shipping code to production. You still need to read what it produces. You still need to understand the context it cannot see. You still need to own the consequences.

If you’re already using AI code generation, extended thinking is a meaningful upgrade worth experimenting with. If you’re skeptical about AI in production code, extended thinking won’t resolve that skepticism. It will only make the case more complicated by giving better tools to your team while exposing everyone to faster iteration cycles. That may be progress, but it’s not an escape from the engineering work that matters.

Have you run extended thinking mode on your own code? I’d be interested in hearing what clicked and what disappointed. Honest assessments from production experience matter more than any benchmark right now.

Google’s Willow Quantum Chip and the Encryption Crisis You Cannot Ignore

What Willow Actually Did, and Why You Should Take It Seriously

In December 2024, Google DeepMind announced the Willow quantum chip, and the internet promptly split into two camps: those who panicked and those who dismissed it as academic theater. Neither response is quite right, but understanding what Willow actually accomplished matters if you’re responsible for any system that needs to remain secure past 2030.

Here’s what happened in technical terms. Willow solved a specific benchmark computation in under five minutes. The same problem would take today’s most powerful classical supercomputers approximately 10 septillion years to complete. That’s a number so large it stops meaning anything to human intuition, but the ratio itself is what matters. This wasn’t a theoretical exercise. The chip physically ran and completed a task in microseconds that represents exponential centuries of serial computation.

But the real story isn’t the speed result. Any sufficiently powerful quantum system solving a carefully chosen problem will eventually outrun classical hardware. What made Willow worth paying attention to was something more fundamental: it demonstrated what quantum engineers call below-threshold error correction. Willow achieved this with 105 qubits by proving that adding more qubits actually reduced errors rather than amplifying them. This is the milestone everyone in the field has been chasing for fifteen years. It means Willow didn’t just solve a hard problem faster. It proved that the path to building quantum computers that won’t destroy themselves with noise is physically real.

Why Quantum Speed Threatens Everything You’ve Built

Let’s talk about RSA encryption, which protects most internet traffic today and locks down the majority of sensitive data at rest in enterprise systems. RSA’s security depends on a mathematical truth: multiplying two large prime numbers together is easy, but factoring the result back into those primes is so computationally hard that no classical computer, given any reasonable amount of time, could do it. This asymmetry has been the bedrock of digital trust for decades.

A sufficiently powerful quantum computer, running Shor’s algorithm, breaks that asymmetry. It can factor those large numbers efficiently. Not eventually. Not in a thousand years. Efficiently, within hours or days, on hardware that might exist in five to ten years. The implications reach every layer of infrastructure: your HTTPS handshakes, your certificate authorities, your SSH keys, your VPN tunnels, your code signing, your database encryption, your regulatory compliance.

This is not a distant threat. The timeline has teeth. Adversaries with nation-state resources are believed to be harvesting encrypted traffic right now, storing it in bulk, waiting for quantum computers powerful enough to decrypt it retroactively. That data might be proprietary source code, customer databases, security audit findings, or strategic communications. The year someone harvests it is the year it all becomes readable. Willow doesn’t make that year next week, but it moves the needle. It proves the path works.

The Migration Hasn’t Started, But the Deadline is Real

In August 2024, the National Institute of Standards and Technology finalized its first three post-quantum cryptography standards: ML-KEM (built on CRYSTALS-Kyber), ML-DSA (built on CRYSTALS-Dilithium), and SLH-DSA (built on SPHINCS+). These are concrete, vetted alternatives to RSA and elliptic-curve cryptography. They’re not theoretical. They’re not proposals. They’re federal standards, which means they’re the reference frame for every government contractor and, eventually, for anyone who wants to sell systems to the government. You can review the NIST post-quantum cryptography standards announcement directly.

The NSA hardened the deadline further in 2022 when it released Commercial National Security Algorithm Suite 2.0, requiring migration to post-quantum algorithms by 2030 for all national security systems. That’s six years from now. For contractors working on defense, intelligence, or critical infrastructure projects, that’s not a suggestion. It’s a compliance mandate with teeth. Miss it and you lose contracts. Worse, your systems might lose certification entirely.

Yet here’s what the January 2025 Ponemon Institute survey found: only 18% of enterprise security teams had begun a formal inventory of their cryptographic assets. That’s the bare minimum prerequisite for migration. You cannot move to post-quantum encryption if you don’t know where your encryption lives. Eighteen percent means 82% of enterprises have done essentially nothing.

What “Migration” Actually Means in Your Infrastructure

This is where the conversation gets uncomfortable, because migration isn’t a software patch you install on a Tuesday and move forward. It’s a systematic replacement of cryptographic foundations across systems that were often built a decade ago and have been reinforced by a thousand dependencies since.

Start with the inventory problem. Where does encryption happen in your environment? Load balancers terminating TLS. APIs issuing JWT tokens. Databases using transparent data encryption. Code signing pipelines. Certificate authorities. Hardware security modules. Message queues. The list sprawls. Each one uses cryptographic primitives. Each one will need to be evaluated, tested with post-quantum algorithms, and replaced or updated.

Then there’s the interoperability problem. You can’t unilaterally migrate everything. You have suppliers. You have partners. You have legacy systems running on hardware that might not support the computational overhead of post-quantum algorithms efficiently. Some embedded systems, older IoT devices, or specialized appliances might be cryptographically locked in. You’ll need hybrid approaches, running classical and post-quantum algorithms in parallel for years. That’s cost. That’s complexity. That’s surface area for mistakes.

The timeline gets compressed further by supply chain dynamics. If your organization is competing for resources and expertise with thousands of other enterprises all trying to migrate simultaneously, prices go up. Talent gets scarce. Projects slip. This is already happening in the compliance consulting space.

What You Should Do Monday Morning

Willow is real, but it’s not an emergency. It’s a signal that the timeline is contracting faster than most organizations realize. The quantum threat isn’t imminent, but the migration work is.

Start with the inventory. Work with your security team, your infrastructure teams, your application owners. Map where cryptography actually lives. Document everything. Prioritize assets that protect the most sensitive data or have the longest operational lifespans. Get it organized somewhere you can actually act on it.

Then run a pilot with post-quantum algorithms. Take a non-critical system. Test ML-KEM or ML-DSA. Measure performance. Document integration challenges. Gather real data about whether post-quantum cryptography introduces operational friction your organization needs to solve for before you’re doing this under deadline pressure.

Budget for this work. The compliance deadline of 2030 for national security systems is six years away, but the practical deadline for large-scale migration is closer. If you’re starting from zero now, you’re already behind. If you’ve been moving incrementally, you’re in a reasonable position to accelerate.

The Willow announcement mattered because it proved quantum computing’s path is real, not because it broke your encryption tomorrow. But it removed one layer of speculation from the timeline. The work of replacing that encryption is yours to do today. What’s the current state of your cryptographic inventory? And more importantly, what’s stopped you from making it a priority until now?

Six Months with Claude 3.7 Sonnet’s Extended Thinking: When the AI Slows Down to Speed You Up

The February Release and What Actually Changed

Anthropic released Claude 3.7 Sonnet in February 2025 with a feature they called extended thinking mode, and if you’ve been paying attention to the AI space, you know that whenever a major lab adds significant latency to their flagship model, something genuinely different is happening under the hood. What they built here is the ability for the model to allocate up to 128,000 tokens to internal reasoning before it ever generates a response you see. Think of it as giving the model a scratchpad that works in real time, the same way you might work through a difficult architectural decision on a whiteboard before committing anything to code.

The timing matters. By early 2025, the industry had settled into a comfortable rhythm with large language models. Fast, mostly accurate enough for obvious tasks, and people had developed strong opinions about where they could and could not be trusted. Then Anthropic released this, and the conversation shifted immediately. The question stopped being “is the AI good enough” and became “what are you actually trying to do, and how much latency can you actually tolerate.”

Performance Metrics and the Real-World Scoring That Matters

On the technical benchmarks, Claude 3.7 Sonnet scored 70.3 percent on SWE-bench Verified, the highest score any AI coding assistant has achieved at launch. If you’re not familiar with SWE-bench, take a look at the SWE-bench Verified leaderboard to understand what we’re measuring here. This isn’t a synthetic coding quiz. These are real, open-source software engineering problems that require the model to understand existing codebases, reason about architectural constraints, and generate patches that actually work. A 70.3 percent success rate on that benchmark means something genuinely different than an 85 percent score on a multiple-choice test.

But here’s what the benchmarks don’t capture, and this is where six months of production use teaches you something the lab reports cannot. The difference between 70.3 percent correct and 85 percent correct on these problems isn’t statistical noise. When you’re shipping code, that gap means the difference between code review feedback that says “this looks solid, minor nit on line 47” and code review feedback that says “this fundamentally misunderstands how our error handling works.” The extended thinking tokens are doing something real in those edge cases.

The Latency Reality and When It Breaks Your Workflow

Extended thinking mode adds between 15 and 45 seconds of latency per complex query on average. That’s not a rounded-for-effect number. That’s what the production telemetry actually shows when you’re using it at scale. Sometimes it’s faster. Sometimes, on genuinely difficult reasoning problems, the model uses most of those 128,000 tokens and the latency creeps toward the upper bound. The first time you experience this, it feels slow. The fiftieth time, you stop noticing the time and start noticing the quality of what comes back.

Six months in, I’ve watched engineering teams split into two camps on this exact question. The first camp, usually teams working on internal tooling or offline batch processes, finds the latency completely acceptable. Their reasoning is straightforward: if the code I generate needs fewer revisions, and I’m not waiting for a human to review it anyway, then spending an extra 30 seconds per query saves time overall. The second camp, usually teams building user-facing features or real-time integrations, finds that extended thinking doesn’t fit their development workflow. They’d rather iterate quickly with a slightly less accurate model than wait half a minute for each response, even if that half minute gets them better code.

Both positions are defensible. This isn’t a case where one group is right and the other is wrong. It’s a case where the technology enables genuinely different tradeoffs, and you have to understand your own constraints well enough to choose the right tool for your situation.

Production Bugs and the Trust Problem

GitHub’s 2025 Developer Survey asked over 11,000 developers a simple question: have you shipped a production bug that you attributed to over-trusting AI-generated code? 62 percent of developers using AI coding assistants said yes. That number deserves to sit with you for a moment. It’s not 15 percent. It’s not 40 percent. More than six in ten developers. Some of those bugs were minor. Some were genuinely serious. The point is that the reliability concerns around AI-generated code are not theoretical.

What I’ve observed across six months of production use with extended thinking is that the mode does something unexpected to how people interact with AI-generated code. It doesn’t make them trust it more, exactly. The fact that the model is “thinking” for 30 seconds creates a weird psychological effect where people assume the output must be more reliable. Sometimes it is. Sometimes the model is just being more careful in a way that doesn’t actually address the specific blind spot in the code. The extended thinking tokens don’t protect you from architectural mistakes or domain knowledge gaps. They help with logical consistency and multi-step reasoning. Those are different problems.

The key lesson from six months of watching this play out is that extended thinking requires more discipline, not less. You need to understand what the model is actually reasoning about. You need to review the code with the same care you would apply to any code that touches production systems. The thinking tokens are a gift, but they’re not a guarantee.

The Cost Factor and Why It Matters for Real Projects

Anthropic’s pricing for Claude 3.7 Sonnet with extended thinking runs at $15 per million input tokens and $75 per million output tokens. If you’re using the extended thinking features heavily, that becomes a significant operational expense. A mid-sized engineering team running 50 complex queries a day at an average of 10,000 input tokens and 2,000 output tokens per query is looking at roughly 15 to 20 dollars per day, around 400 to 500 dollars per month just for the API calls. Scale that across an organization, and it’s real money.

The calculus changes depending on where you sit in the organization. For a startup or small team, that’s the cost of a junior developer’s coffee for a month. For an enterprise, it fits into the noise. For someone building a side project or trying to learn something new, it might be too much. Extended thinking is powerful, but it’s not free, and you need to know whether the problem you’re solving justifies the cost.

If you’re just getting started with this tooling, begin with a small, defined project. Pick something where the latency doesn’t break your workflow. Use extended thinking only on the genuinely complex parts of the problem. Learn what kinds of reasoning the model actually benefits from having the extra tokens for, and what kinds of problems you can solve just fine with faster inference. After a month or two, you’ll have enough data to make real decisions about how this fits into your development process.

What has your experience been with extended thinking models, or what questions do you have about integrating them into production systems? I’m curious what problems are pulling you toward this technology and where you’re skeptical. Reach out if you want to dig into specific use cases.